arXivML & AI Methods
AlphaPilot: Multi-Turn Tool-Using LLM Agents for Adaptive Alpha Mining with Reinforcement Learning
A reinforcement-learning framework trains multi-turn tool-using LLM agents to discover factor expressions by conditioning on market descriptions and querying real-data feedback.
Featured in No. 135 on 16 Oct 2026 · 2 days after release
- Released
- 14 Oct 2026
- First featured
- No. 135 · 16 Oct 2026
- Published in
- Not yet, as far as Semantic Scholar knows
- Fanfare
- 3 of 5
- Identifier
- arXiv:2610.15488
- Authors
- Peiqi Jiang et al.
Abstract
From arXiv (CC0).
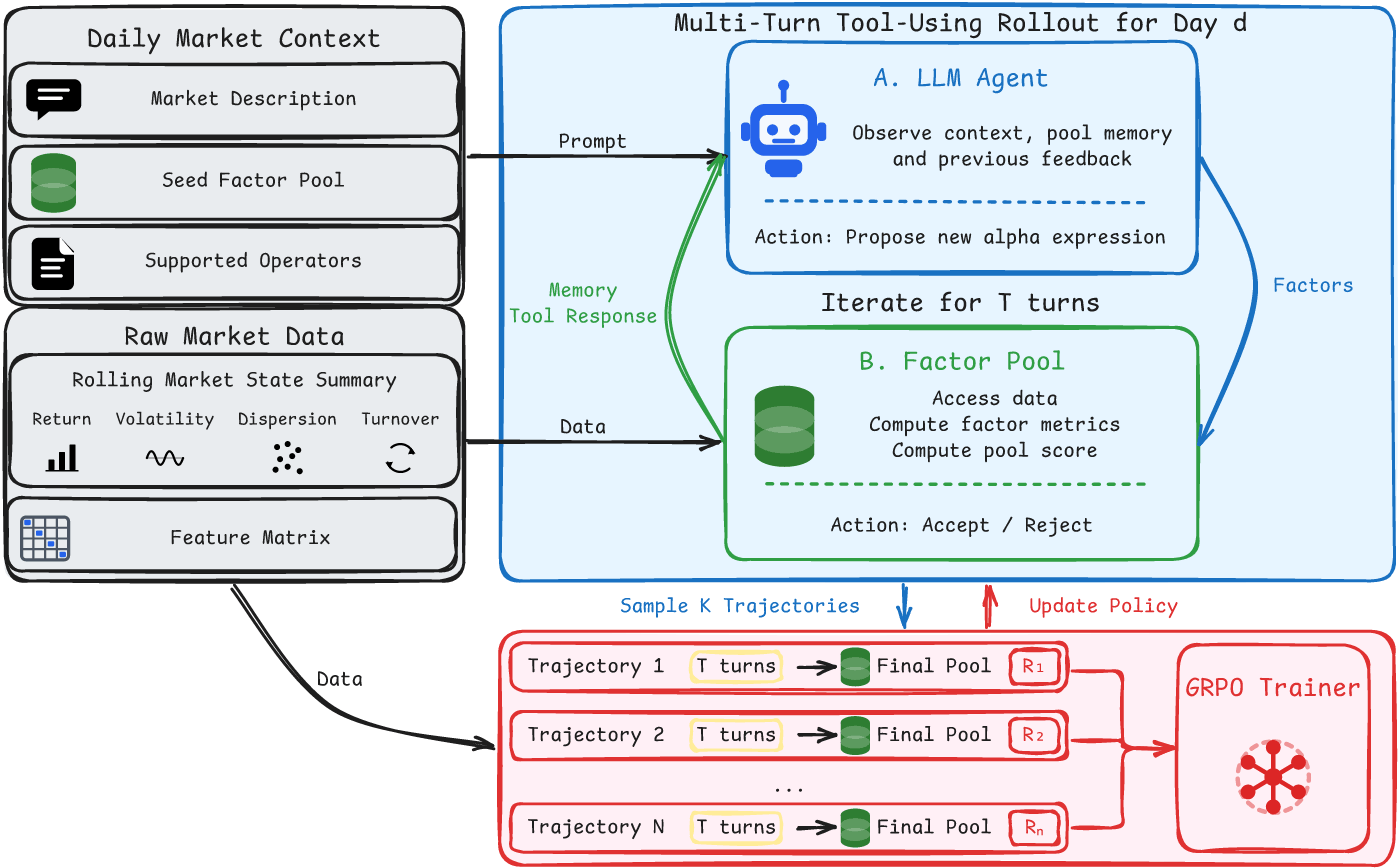
Formulaic alpha mining seeks interpretable expressions that rank assets by future returns. The task is challenging because it demands simultaneous processing of unstructured market descriptions, historical data, and quantitative evaluation of candidate factors, yet most existing methods exploit only a subset of these signals. We introduce AlphaPilot, a reinforcement-learning framework that trains multi-turn tool-using LLM agents for adaptive alpha mining. The agent conditions on market descriptions, proposes factor expressions, queries real-data evaluator feedback, and updates a retained factor pool across turns. This design jointly leverages market text, LLM financial knowledge, real data, and evaluation feedback. At inference time, AlphaPilot performs day-by-day search and pool updates to adapt to shifting market regimes. Across three independent runs in out-of-sample rolling backtests on CSI300 and CSI500, AlphaPilot achieves mean total returns of 42.93% and 54.19%, with mean Sharpe ratios of 2.46 and 2.86, respectively. It attains the highest mean total return, Sharpe, and RankIC among the evaluated methods on both universes.
Citations and venue from Semantic Scholar (ODC-BY), refreshed weekly. Summary: Quant Letter (CC BY 4.0).