arXivLLMs & Text
NoLBERT-Calls: Reading Earnings Calls Without Hindsight
The study adapts a 1976-1995 pretrained encoder to identify management answers to analyst questions in earnings calls through 2026, reaching 78% accuracy versus 8% by chance.
Featured in No. 140 on 20 Nov 2026 · 3 days after release
- Released
- 17 Nov 2026
- First featured
- No. 140 · 20 Nov 2026
- Published in
- Not yet, as far as Semantic Scholar knows
- Fanfare
- 3 of 5
- Identifier
- arXiv:2611.19849
- Authors
- Kevin Foley et al.
Abstract
From arXiv (CC0).
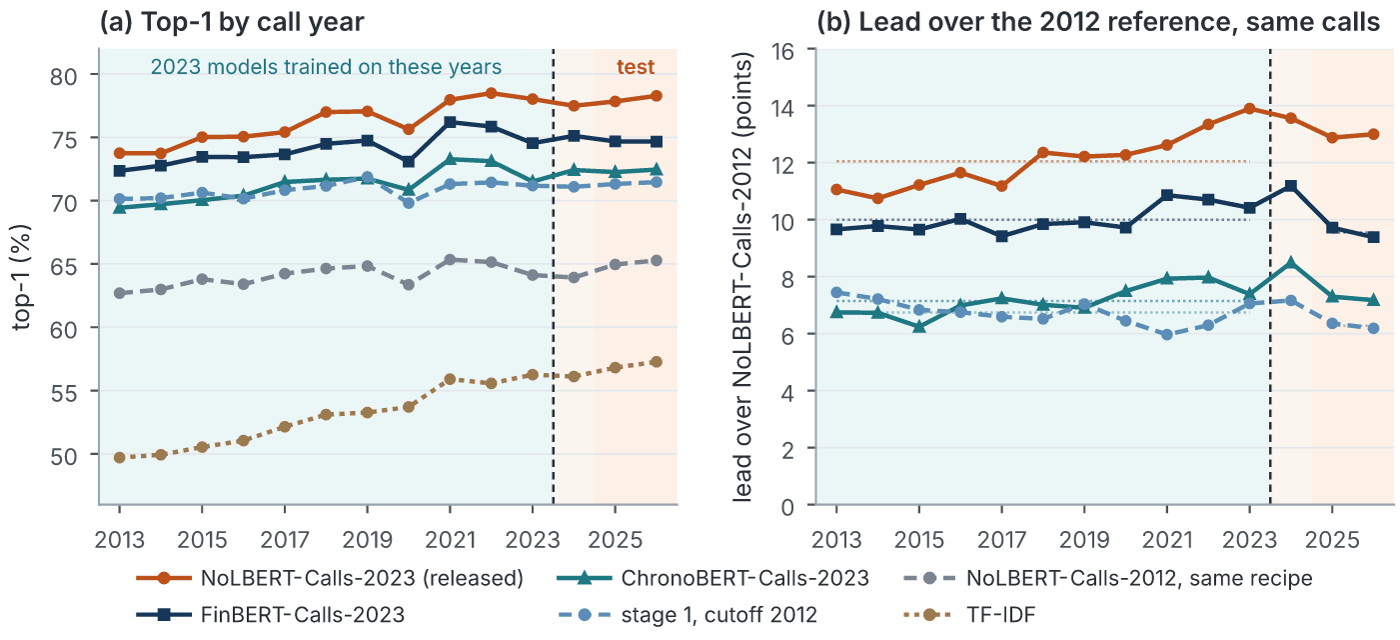
Language models are now a standard tool for measuring what managers say on earnings calls, but the encoders behind these measures were usually pretrained on text from the same years a backtest covers. Holding out a test period does not remove that hindsight, because it sits in the features. We adapt NoLBERT, an encoder pretrained only on text published between 1976 and 1995, to earnings calls without letting it read anything dated after 31 December 2023. The calls supply the training signal themselves: every analyst question is followed by management's answer, and the model learns to pick that answer out from the other answers of the same call. We test on every US call from January 2025 to October 2026 (20,323 calls, 254,575 questions) and make every modeling choice on calls from 2024. The adapted model, NoLBERT-Calls-2023, ranks the true answer first for 78.0% of questions (95% interval 77.8-78.2; chance 8.0%), against 26.3% before adaptation. It is 1.0 point ahead of a call-adapted ChronoBERT, 3.4 points ahead of a call-adapted FinBERT, and 18.7 and 19.8 points ahead of the best off-the-shelf retriever and BM25. A year-by-year test over 2013-2026 finds no look-ahead premium: relative to a model adapted only through 2012, the released model does no better on the years it was trained on than on years it never saw. The price of the cutoff is compute: under one shared 150-minute recipe NoLBERT adapts least well of four encoders, and its lead comes from a longer, staged adaptation of about 13 GPU-hours.
Citations and venue from Semantic Scholar (ODC-BY), refreshed weekly. Summary: Quant Letter (CC BY 4.0).