arXivML & AI Methods
BuySideFlow: A Point-in-Time Benchmark for LLM Agents in Investment Research
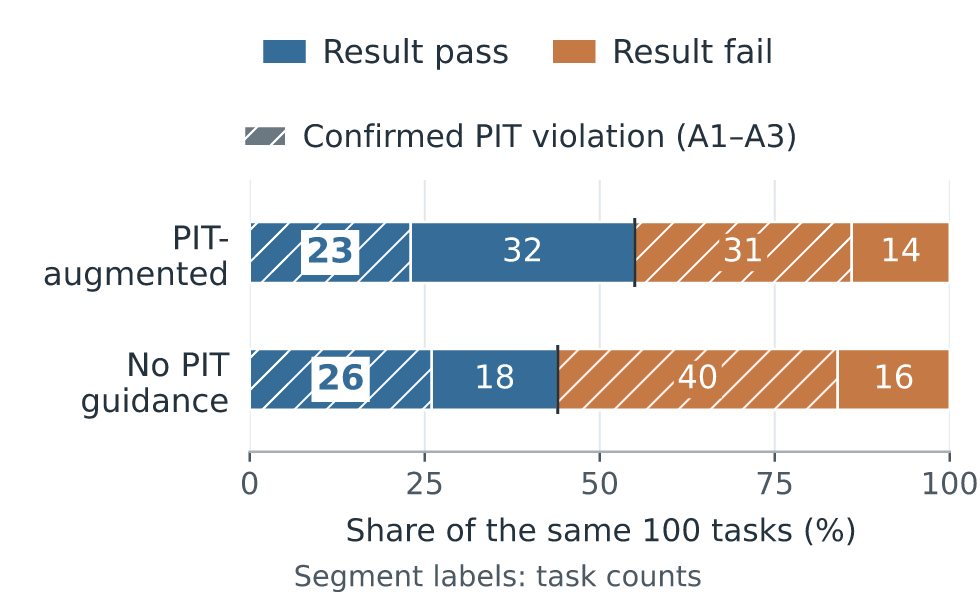
Evaluates LLM agents on 408 investment research tasks, finding that half of workflows passing result checks contain temporal violations, revealing a 50.8% gap between output agreement and temporal validity.
Featured in No. 139 on 13 Nov 2026 · 2 days after release
- Released
- 11 Nov 2026
- First featured
- No. 139 · 13 Nov 2026
- Published in
- Not yet, as far as Semantic Scholar knows
- Fanfare
- 3 of 5
- Identifier
- arXiv:2611.12966
- Authors
- Dong Bo et al.
Abstract
From arXiv (CC0).
Large language models (LLMs) can generate SQL and SQL--Python workflows for investment research, but ensuring point-in-time (PIT) validity remains challenging. Agents must enforce disclosure cutoffs and select the appropriate historical states and record versions throughout data retrieval and financial analysis. We introduce \textsc{BuySideFlow}, a benchmark of 408 practitioner-derived Chinese-language tasks spanning equities, funds, fixed income, and macroeconomics over a fixed snapshot from a licensed production financial database. We provide executable references and a taxonomy of temporal errors, pairing result checks with expert audits of executed workflows. We evaluate nine agent configurations on all tasks, with result accuracy ranging from 16.2\% to 36.8\%. An audit of 900 runs on 100 shared tasks confirms PIT violations in 193 of the 380 runs that pass result checks (50.8\%), showing that output agreement alone does not establish temporal validity.
Citations and venue from Semantic Scholar (ODC-BY), refreshed weekly. Summary: Quant Letter (CC BY 4.0).